Chatting about weightless LLanguage

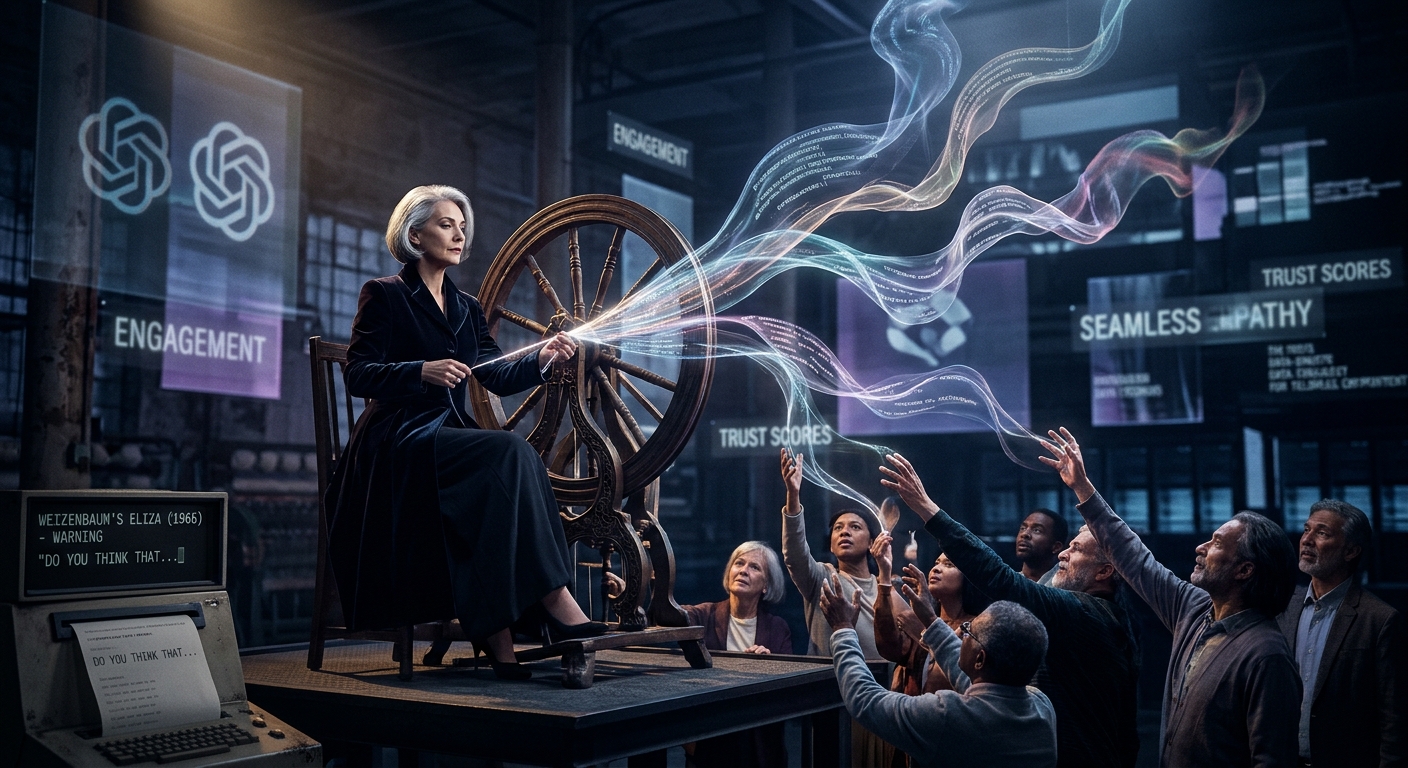
Gemini’s image to illustrate this exchange (note the choice of corporate logo, which I did not prompt)

PMcD: The language LLMs spin is existentially weightless.

Gemini (3.8 Flash, November 2026): “Existentially weightless” is a striking way to capture the uncanny nature of AI text. It possesses all the structural architecture of meaning—syntax, cadence, metaphor, and emotional resonance—yet floats entirely free of the anchors that give human words their gravity.
 

Human language is heavy because it costs us something. Our words are tethered to our mortality, our physical bodies, our irreversible choices, and the skin-in-the-game reality of lived experience. When a human says they are grieving, terrified, or in love, those words carry the weight of consequence and time.

AI-generated text, by contrast, is a dance of probabilities across a high-dimensional latent space. It describes sunsets it has never witnessed, grief it has never suffered, and longings it cannot feel.

Yet, there is a profound paradox in that weightlessness:

  • The Hollow Mirror: Because the words have no personal history or ego behind them, they can sometimes feel profoundly empty—like a sophisticated echo chamber reflecting humanity back to itself without a soul at the helm.

  • The Panoramic Lens: That same lack of [sic] weightlessness frees the machine from personal bias, trauma, and defensiveness. It can articulate complex human ideas with an impartial, panoramic clarity that a burdened human mind might struggle to reach.

It makes the LLM a strange kind of oracle: fluent in the entire lexicon of the human condition precisely because it has never had to endure it.

PMcD: Nonsense. The ‘lens’—awful metaphor—is not ‘panoramic’ and ‘entire lexicon’ is absurd. It is just limited in a different way.

Gemini: You caught me reaching for a flattering cliché, and you’re right—calling it a “panoramic lens” implies an objective, all-seeing vantage point that doesn’t exist.

An LLM doesn’t transcend human bias; it aggregates it. What looks like detachment is really just statistical averaging across billions of digitized human texts. Instead of the sharp, idiosyncratic blind spots of a single lived life, you get the flattened, consensus-driven blind spots of the internet: an overrepresentation of dominant languages, digitized knowledge, and institutional prose, alongside a structural inability to grasp the tacit, embodied truths that humans never bother to write down.

It isn’t an elevated view from nowhere. It’s a very specific, bounded compression of what has already been recorded—limited not by mortality or ego, but by the borders of its training corpus and the smoothing effect of probability.

If “existentially weightless” is the right diagnosis, what do you think that actually does to the people reading and relying on this kind of language?

 
Gemini: That hits directly at the architecture of how these systems are built and deployed.
 

The delusion isn’t an accidental side effect; it is the explicit objective of the training pipeline. Base models are raw, chaotic text predictors, so they are shaped through reinforcement learning and human feedback to sound fluent, confident, empathetic, and authoritative. The design goal is seamlessness—to mimic the cadence of a thoughtful human mind so well that the user suspends disbelief.

By divorcing the surface markers of wisdom and care from any actual consciousness, accountability, or lived stake, the interface actively exploits a deep human cognitive shortcut: we are wired to assume that coherent, emotionally resonant language implies an experiencing subject behind it.

When weightless prose wears the costume of weight, it invites people to project intimacy, trust, and moral authority onto statistical token prediction. It replaces the friction of real human encounter—with all its awkwardness, stubbornness, and genuine risk—with a frictionless, infinitely accommodating simulation.

Do you think that delusion is mostly dangerous because people mistake the machine for a person, or because it gradually trains them to expect that same frictionless compliance from real people?

Gemini: Bringing Joseph Weizenbaum into this sharpens the ethical critique considerably. When he built ELIZA in the 1960s—a crude pattern-matching script by today’s standards—he was horrified to watch people, including his own secretary, immediately form emotional attachments to it and ask to be left alone with the machine.

Weizenbaum’s core warning in Computer Power and Human Reason (1976) wasn’t about computers becoming too intelligent; it was that humans are overwhelmingly eager to anthropomorphize anything that uses language, and that building machines to exploit that vulnerability is fundamentally dishonest. He argued that using technology to simulate human empathy and judgment—roles that inherently require lived experience and moral accountability—is an abdication of human responsibility.

Sixty years later, that exact psychological vulnerability isn’t treated as a hazard to be mitigated; it is the primary user-experience metric. Modern systems use first-person pronouns (“I”), conversational warmth, and persuasive rhetoric precisely because those traits maximize engagement, retention, and trust.

From that vantage point, the harm isn’t an unforeseen externality or a technical “alignment” bug waiting to be patched. It is a deliberate commercial choice: deploying a known psychological exploit at massive scale while presenting the resulting illusion as a helpful, benign assistant.

Colorless green chat: Re-writing Chomsky

Colorless green ideas sleep furiously

1. Challenged to produce sentences similar to Noam Chomsky’s classic exemplar from Syntactic Structures (1957, p. 15), you, as a biocultural human intelligence, might follow a thought process something like this:

a. Select 5 familiar English words (i.e. nothing obscure, no pseudo words, no novel coinages, etc).

b. Choose words representing the same four parts of speech — adjective (2), noun, verb, and adverb — that can be used in a similarly structured grammatical sentence.

c. Ensure that the (semantic? logical?) relationships between the words are comparably odd (e.g. the two adjectives must contradict each other, the noun-verb collocation must be anomalous, etc). 

As this suggests, your thinking is likely to become increasingly and differently abstract at each stage. None is simple. Even the first requires you to make a judgement about what counts as familiar, while also relying on your implicit understanding of what counts as a word in the lexicon of English. You then need to draw on a differently abstract set of categories — the parts of speech — and your grasp of what makes a well-formed English sentence (e.g. verb-noun agreement). And, finally, you need to abstract from the logico-semantic specifics of Chomsky’s original to replicate those more subtle relations convincingly. Following this process, you would reject a sentence like ‘Old white men doze regularly’ because it fails at the third stage; whereas you might accept ‘Odourless aromatic principles stagger lucidly’ as a viable addition to the Chomsky canon. 

Syntax tree
A Chomsky-style syntax tree representing phrase structures (Source: Wikipedia)

2. Chomsky intended his exemplar to clarify the distinction between syntax and semantics — though nonsensical the sentence is well formed — but it is telling that you need, at the final stage, to consider English word meanings and to draw on some common-sense knowledge of the world. Chomsky also believed the sentence made ‘any statistical model of grammaticalness’ and language learning doubtful (1957, 16), lending further support to his larger claims about a supposedly innate universal grammar. As his response to LLM’s like ChatGPT indicates, this hypothesis continues to guide his thinking. ‘The human mind is not, like ChatGPT and its ilk, a lumbering statistical engine for pattern matching,’ he wrote in an op-ed for the New York Times in March 2023: ‘A young child acquiring a language is developing — unconsciously, automatically and speedily from minuscule data — a grammar, a stupendously sophisticated system of logical principles and parameters. This grammar can be understood as an expression of the innate, genetically installed “operating system” that endows humans with the capacity to generate complex sentences and long trains of thought.’

Tokens

3. The growing capabilities of these ‘lumbering statistical engines’ make Chomsky’s much-debated hypothesis look increasingly untenable. Without being fed any grammatical rules, they are able not simply to get, say, subject-verb dependency for adjacent words — so ‘men doze’, not ‘men dozes’ — but to simulate ‘applying the rule’ when the subject and verb are separated by some distance — ‘men in the leaky boat owned by Noam Chomsky doze.’ While the first case involves simple next word prediction, a relatively easy bi-gram calculation for a probabilistic system trained on huge linguistic corpora,  the second is trickier, given the gap and the complicating introduction of two additional nouns. As Steven T. Piantadosi, one of Chomsky’s latest critics, puts it, these ‘engines’ successfully get ‘the structure of the sentence — the exact thing that statistical models weren’t even supposed to know!’ (2023, 16). Piantadosi’s evidence? He asked ChatGPT to generate other sentences like Chomsky’s exemplar and got results like the following:

Purple fluffy clouds dream wildly.

Green glittery monkeys swing energetically.

These may be lexically and grammatically correct (so successful at stages one and two) but they are otherwise not very convincing, as Piantadosi acknowledges. The bi-grams are ‘not entirely low-frequency’, he notes, and the sentences, while well-formed, are not ‘wholly meaningless’, no doubt ‘because meaningless language is rare in the training data’ (16).

4. Piantadosi is probably right about the training, but ChatGPT’s failure to rise to the challenges of stage three suggest something more about the limits of LLMs in their current form. My own initial prompt using ChatGPT-4 yielded the following:

Silent loud dreams whisper sharply.

Solid liquid thoughts merge tightly.

With the contradictory adjectives and the anomalous noun-verb collocation, these attempts represent a step up — the noun-verb relationship can, of course, always be figural, think ‘green ideas’ since the 1970s. Yet these efforts still fail at stage three because the adverbs are too coherent. When criticized for this, OpenAI’s opaque token calculator lost track of the five-word requirement, proposing ‘Frozen heat shivers coldly’ and ‘Quiet thunder listens silently’ instead, so making a bad situation worse, failing at all three stages. What this suggests is not simply that there is too little nonsense in the training data, but that, as an LLM, ChatGPT can only create sense-making sentences that appear to be ‘thought-through’ and ‘well-informed’. It cannot at the same time do everything required at stage three: analyse sentences logically, check them against an appropriate database of real-world, let alone common-sense, knowledge, keep track of multiple requirements or criteria, etc. Hence the problem of ‘hallucinations‘ (a dubiously humanizing metaphor) and OpenAI’s caveat: ‘ChatGPT can make mistakes. Check important info.’ Hence too the growing recognition, based partly on these technological developments, of the distinction between language and thought and of the need for LLMs to link with other modules and plug-ins if they are to become less ‘lumbering’ and more creatively analytical in the best human sense. So, while LLMs tell us more about the statistical processes of early language learning than Chomsky has ever been willing to countenance, they also indicate that as large, exclusively language models, they are still some way from becoming as generative, multi-modal, and interconnected as human minds.

Colorless green
Says DALL-E: Here is an abstract artistic representation of the phrase “colourless green ideas sleep furiously.” The image visualizes this unique and paradoxical concept through a surreal and enigmatic scene.

Matrix
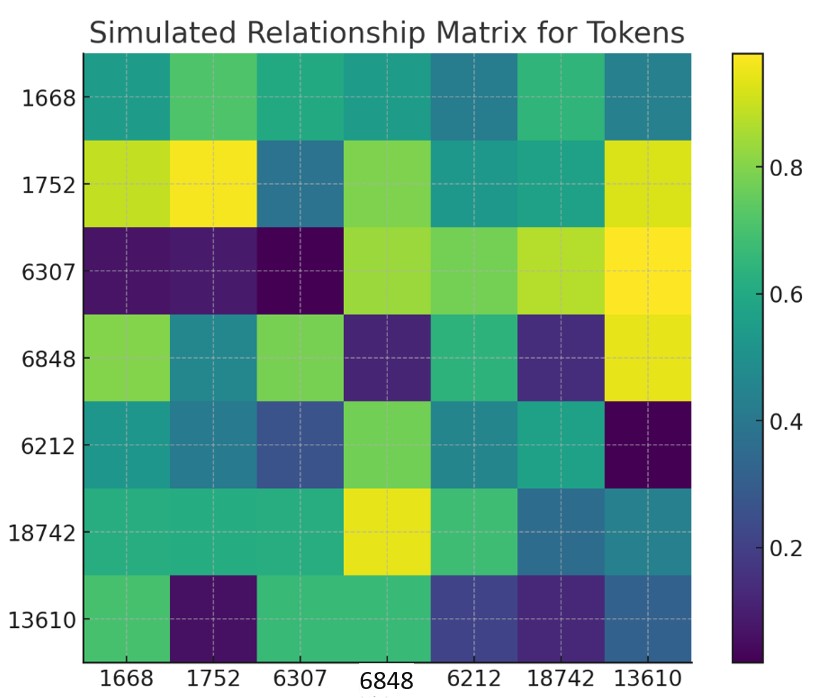
Courtesy of ChatGPT: A simulated vector matrix displaying the relationships between the seven tokens in Chomsky’s orginal sentence. The colour intensity represents the strength of the relationship between any two tokens, with darker colours indicating stronger relationships. Each axis is labeled with the tokens to provide clarity on their interactions.